Bangladesh National Corpus (BDNC)
The Bangladesh National Corpus (bdNC) is a comprehensive collection of Bangla text under the "Bangla Syntactic Treebank Corpus with Processing Pipeline and Distribution Platform" project. This morphologically rich corpus is designed to be non-duplicate, balanced, and representative across various domains, time periods, and text types. The total size of the corpus will reach 40 gigabytes, encompassing 3 billion words or more.
Data Cardinality
| Type | Count |
|---|---|
| words | 3609011064 |
| sentence | 382031994 |
| documents | 15792763 |
| number of unique words | 11668887 |
| number of domain | 41 |
| number of source | 187 |
| text size | 57.10 GB |
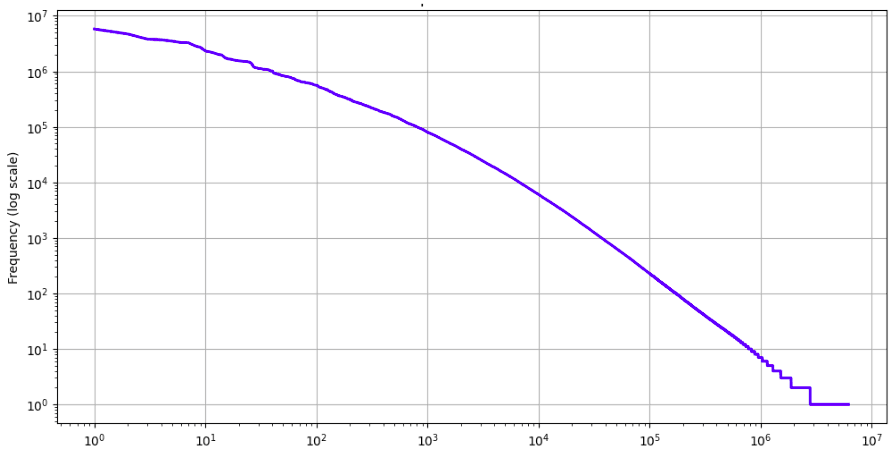
Zipf's distribution
The following figure depicts the Zipf's distribution on the corpus.
Metadata
Each text in the corpus will be delivered as JSON objects each having some specific attributes. Some of the major attributes of each datapoint are given below.
| Attribute | Optional | Description |
|---|---|---|
| _id | no | Unique identification string of the data entry. |
| url | no | Source URL. |
| title | no | Title of the document. |
| domain | no | Domain of the document. |
| source_type | no | Type of the source. |
| source | no | Site or source name. |
| author | yes | The author name of the content. |
| text | no | The raw text content from the site. |
| summary | yes | Summary of the parsed text. |
| categories | yes | Categories the text falls in. |
| word_count | yes | Number of words. |
| parse_time | no | The date and time when the data was parsed. |
| publish_date | yes | The date and time when the data was published on the site. |
Source Type Distribution
The following table shows the distribution of each domain according to word count, document count and sentence count.
Source distribution
The following figures depict the source-wise word count distribution.
Domain Distribution
The following figures depict the source-type-wise word count distribution.
Time distribution
The following figure illustrates the year-wise data distribution of the corpus.